MiniMax just put the weights of a video model on Hugging Face that makes its own sound. MiniMax H3, from the team behind Hailuo AI, generates the picture, the dialogue, the sound effects and the music in a single pass.
Most open video models are silent. You generate the clip, then you go find a separate tool for voice and audio, then you try to line it all up. H3 outputs 32 kHz stereo audio with the video, in clips of 4 to 15 seconds at 24 frames per second.
One transformer for picture and sound
The core is the H3 Omni Transformer, a 33 billion parameter dense model. It predicts the video latents and the audio latents jointly, then separate decoders turn them into frames and a stereo track. Because both come out of the same model at the same time, the lip sync is built in.
MiniMax lists stable dialogue support for 11 languages: Arabic, Chinese, English, French, German, Italian, Japanese, Korean, Portuguese, Russian and Spanish.
There is also a practical detail for anyone who wants to run it. About 13 billion of those 33 billion parameters sit in AdaLN branches whose outputs can be precomputed, so an inference only deployment does not need to load them.
The 2K trick, and what is actually open
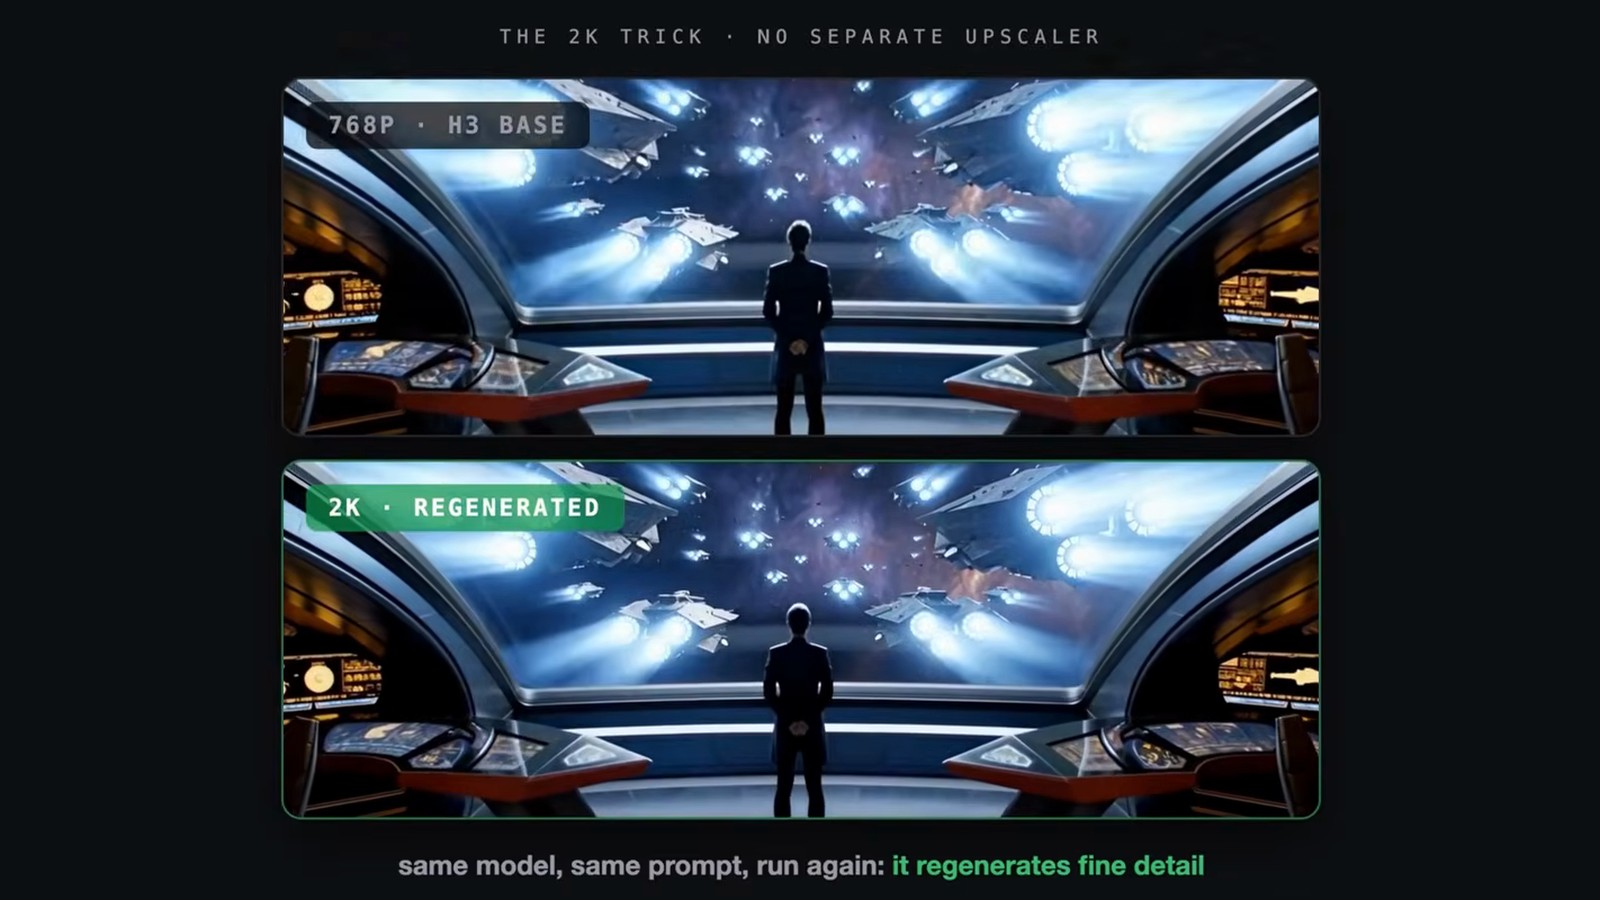
H3 does not use a separate upscaler for 2K. The base model first generates at 768p (the short side). Then a module called H3 Regenerate 2K feeds that 768p result plus your original prompt and references back through the same model, so it regenerates fine details like small text instead of guessing them.
The reference mode is the other strong part. One request can take up to 9 images, 3 video clips and 3 audio clips, with a limit of 12 files in total. That covers character consistency, a voice reference, and even editing an existing video so a person speaks new lines.
The catch
Read the model card before you plan a local setup. Three things matter:
- The open checkpoints stop at 768p. The Regenerate 2K module is not open source yet. For now, 2K output goes through the MiniMax API.
- The prompt system is hosted. H3 Context IR, the system that turns your messy inputs into the structured prompt the base model expects, is not in the release. MiniMax says it is critical to output quality and gives a prompting guide to build your own.
- The license has a region limit. The open weight license currently does not cover the US, the EU, the UK and South Korea. Organizations there must apply to MiniMax for a formal license. The API stays available everywhere.
So "open weights" is true, with conditions. If you are outside those four regions and have the GPUs, you can run the 768p model today through SGLang, vLLM, diffusers or ComfyUI. Everyone else gets the API, or the application form.