Alibaba just released a 2.4 trillion parameter model that finished ahead of 87% of human teams in a real competition. It is called Qwen 3.8 Max, the biggest model Qwen has ever built, and for the first time Qwen is releasing the weights of a Max class model.
It is a mixture of experts model with 95 billion parameters active per token. At launch, Alibaba said the weights would follow the next week. They are now on Hugging Face as Qwen3.8 2.4T A95B.
16 days with no human help
Qwen gave the model an empty repository and told it to build a CLI tool called oh-my-cli. By July 30, after about 16 days of fully autonomous operation, the repo had 265 commits, 127 pull requests and 151 issues. The model opened, worked and closed them itself.
The contest and the paper
Next, Alibaba entered it in the WWW2025 Multimodal Dialogue Intent Recognition Challenge on its Tianchi platform. 526 human teams competed. The task was to read customer service chats, text and screenshots, and work out what the customer wants. Under a 24 hour limit, the model built its own ensemble of fine-tuned models, made 45 submissions, and moved its accuracy from 0.60 to 0.853. That put it ahead of 458 of the 526 teams.
It also reproduced a research paper from scratch in about five days (roughly 125 hours of work), confirmed the paper's six main findings, and then tested 18 of its own ideas. The best one beat the paper's method by 2.71 points on AIME24.
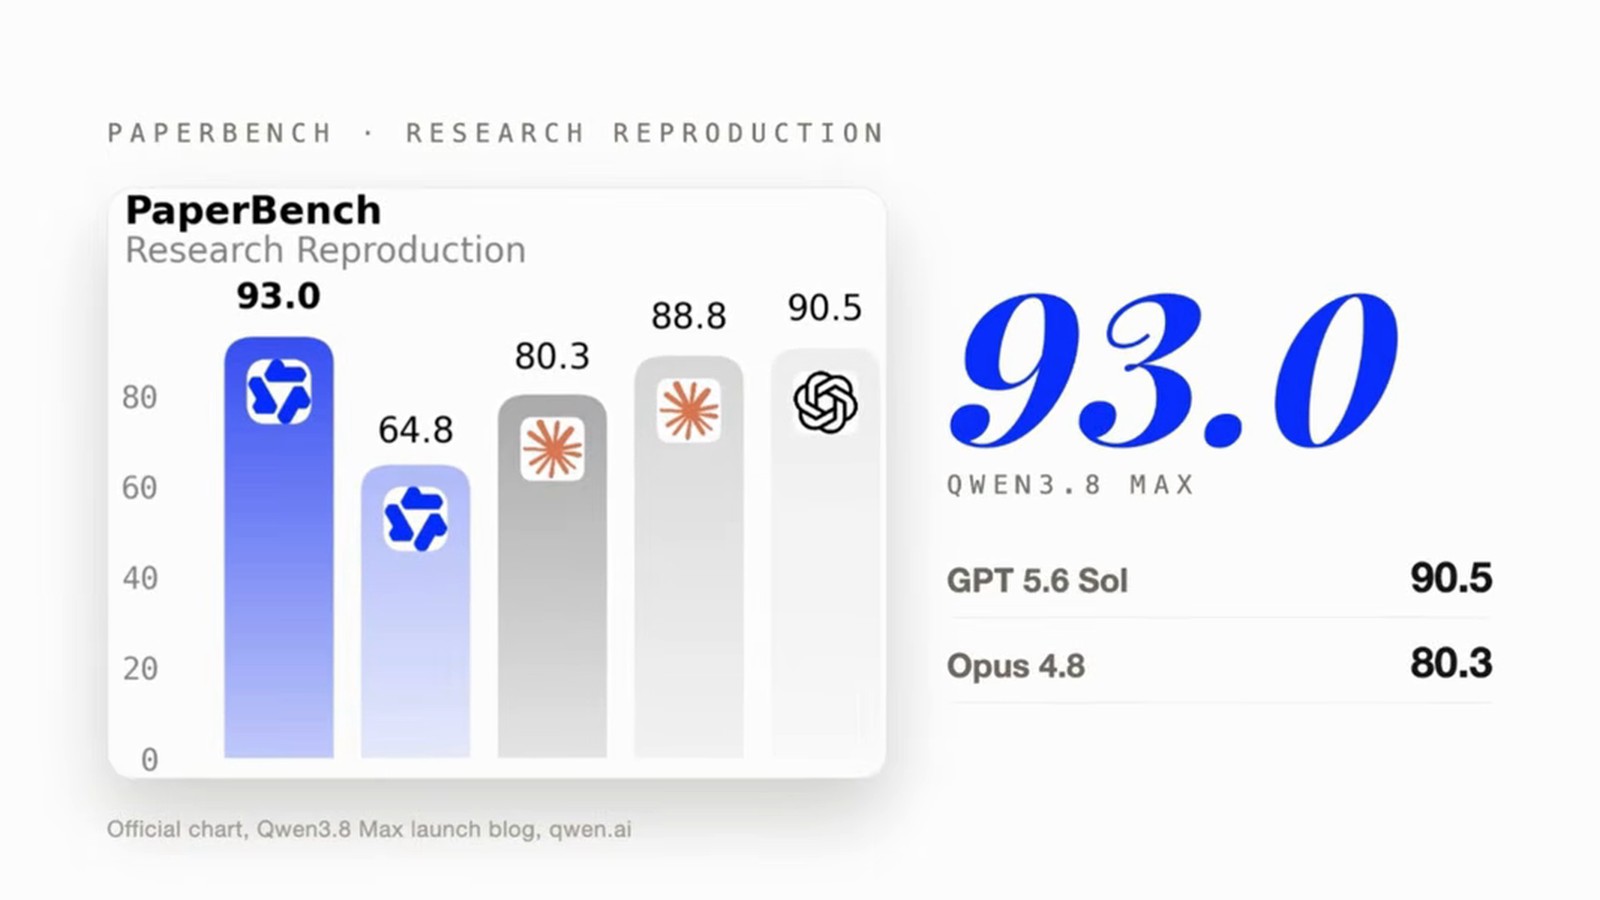
On PaperBench, the benchmark for reproducing research papers, it scores 93.0. That is above GPT 5.6 Sol at 90.5, Claude Fable 5 at 88.8 and Claude Opus 4.8 at 80.3.
Point Claude Code at it
The hosted Qwen3.8 Max API has a 1 million token context window by default, and Qwen's API speaks the Anthropic protocol. The official setup is four environment variables (model, small fast model, base URL and auth token), and then you run claude as usual.
The catch
Every number here comes from Alibaba's own launch materials. And the coding lead is not universal. On SWE-bench Pro, Qwen 3.8 Max scores 67.7 against 80.0 for Fable 5, and it trails Fable 5 on most of the general agent benchmarks in its own table.
"Open weights" also does not mean "runs on your laptop". The checkpoint is about 4.9 TB in BF16. The open version also differs from the API model: its native context is 262,144 tokens, extensible to about 1 million, and features like vision input and the built-in tools belong to the hosted Qwen3.8 Max.
For most people, the API through Claude Code is the realistic way to try it.
Read the Qwen 3.8 Max launch post
If you build with coding agents like this, the AI Academy community is where I share my setups: AI Academy with Robby.