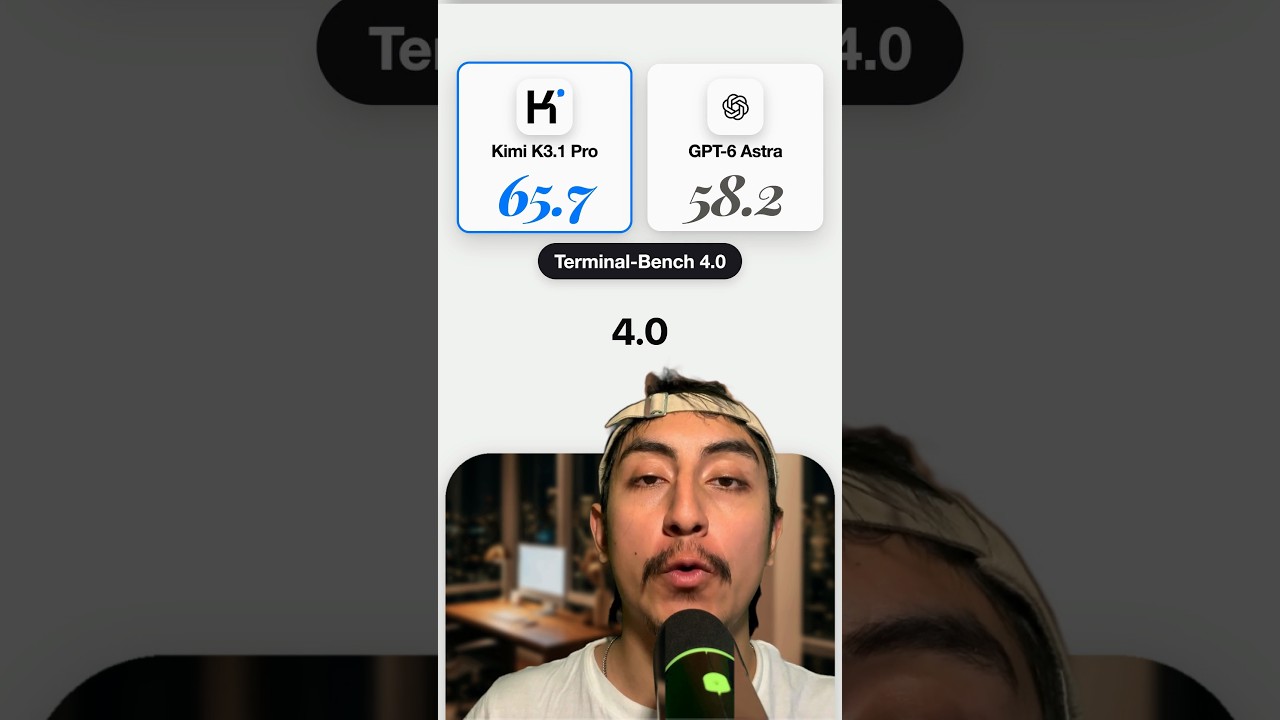
Kimi K3.1 Pro just beat GPT-6 Astra on Terminal-Bench 4.0, and Moonshot AI says its weights go public by November 4.
What K3.1 Pro is
Kimi comes from Moonshot AI. In their announcement, they call K3.1 Pro "our most capable 3T-class open-weight model to date, with a 1-million-token context window."
You can use it today in the Kimi app, Kimi Work, Kimi Code and the Kimi API.
The score
Terminal-Bench 4.0 gives coding agents real terminal tasks with strict tests. Here is how the top of Moonshot's chart looks:
- Claude Opus 5.5: 66.4%
- Kimi K3.1 Pro: 65.7%
- GPT-6 Astra: 58.2%
So K3.1 Pro is 7.5 points ahead of GPT-6 Astra, but Claude Opus 5.5 still leads, by 0.7 points.
The catch
These are Moonshot's own numbers. Three details from the footnotes matter:
- The harness. Moonshot says K3.1 Pro was evaluated with the Claude Code harness.
- The rival scores. The other scores are "taken as the maximum value reported in either their blog posts or the official Terminal-Bench 4.0 leaderboard." So the rivals were not all rerun under the same setup.
- The settings. The chart note says all models were maxed out on thinking effort, and that Claude models may include fallbacks and GPT models may include cyberguards.
And this is one coding benchmark. It does not prove K3.1 Pro beats GPT-6 Astra at all coding. The fair reading is: on this test, by Moonshot's measurement, it is close to the top.
The weights
This is the part I care about most. Moonshot says "the full model weights will be released by Nov 4, 2026." When I made this video, they were not out yet.
When they land, anyone can download and host a model that sits 0.7 points behind Opus 5.5 on this test. But be realistic about the hardware. A 3T class model is not something you run on a laptop. You will need serious hardware, or a provider that hosts it for you.
I made the same point about the earlier release in Kimi K3 is open source, you still can't run it. Open weights and "runs on my machine" are two different things.
How I would test it
Do not trust the headline, mine included. Open Kimi Code or the Kimi API, pick K3.1 Pro, and give it one real task from your own repo. Then give the same task to the model you already use and compare the results. That tells you more than any single chart.
For another model that scored well on a narrow test, see my post on Qwen 3.8 Max beating 87% of human teams.
Sources: Kimi K3.1 Pro announcement (Moonshot AI), Kimi
Watch the Short above for the walkthrough. If you want the Claude Code skills and workflows I use to automate my content and my business, join the AI Academy community on Skool.